
GLM-5.2
GLM-5.2 is the flagship model built for the long-task era, featuring a truly usable 1M context window and 128K max output tokens. With GLM-5.2, developers can complete the entire development chain from requirements to deployable artifacts in a single continuous task. GLM-5.2 keeps engineering standards reliable across extended sessions.
Feedback
freeTrialImage.bannerPity
freeTrialImage.upgradeUnlock
- ✓freeTrialImage.benefitHd
- ✓freeTrialImage.benefitWatermark
- ✓freeTrialImage.benefitUnlimited
All Tools
Discover our comprehensive AI-powered animation toolkit
Muse Video
Seedance2.5
The Future of AI Video Is Here.

Seedance 2.0
The Future of AI Video Is Here.

Veo3.1
Create Stunning Videos with Veo3.1
Grok Video Generator
Create Videos from Text or Images with AI
MiniMax H3 video generator
MiniMax H3 AI Video Generator

Seedance 2.0
The Future of AI Video Is Here.

Gemini Omni 1.2 Flash
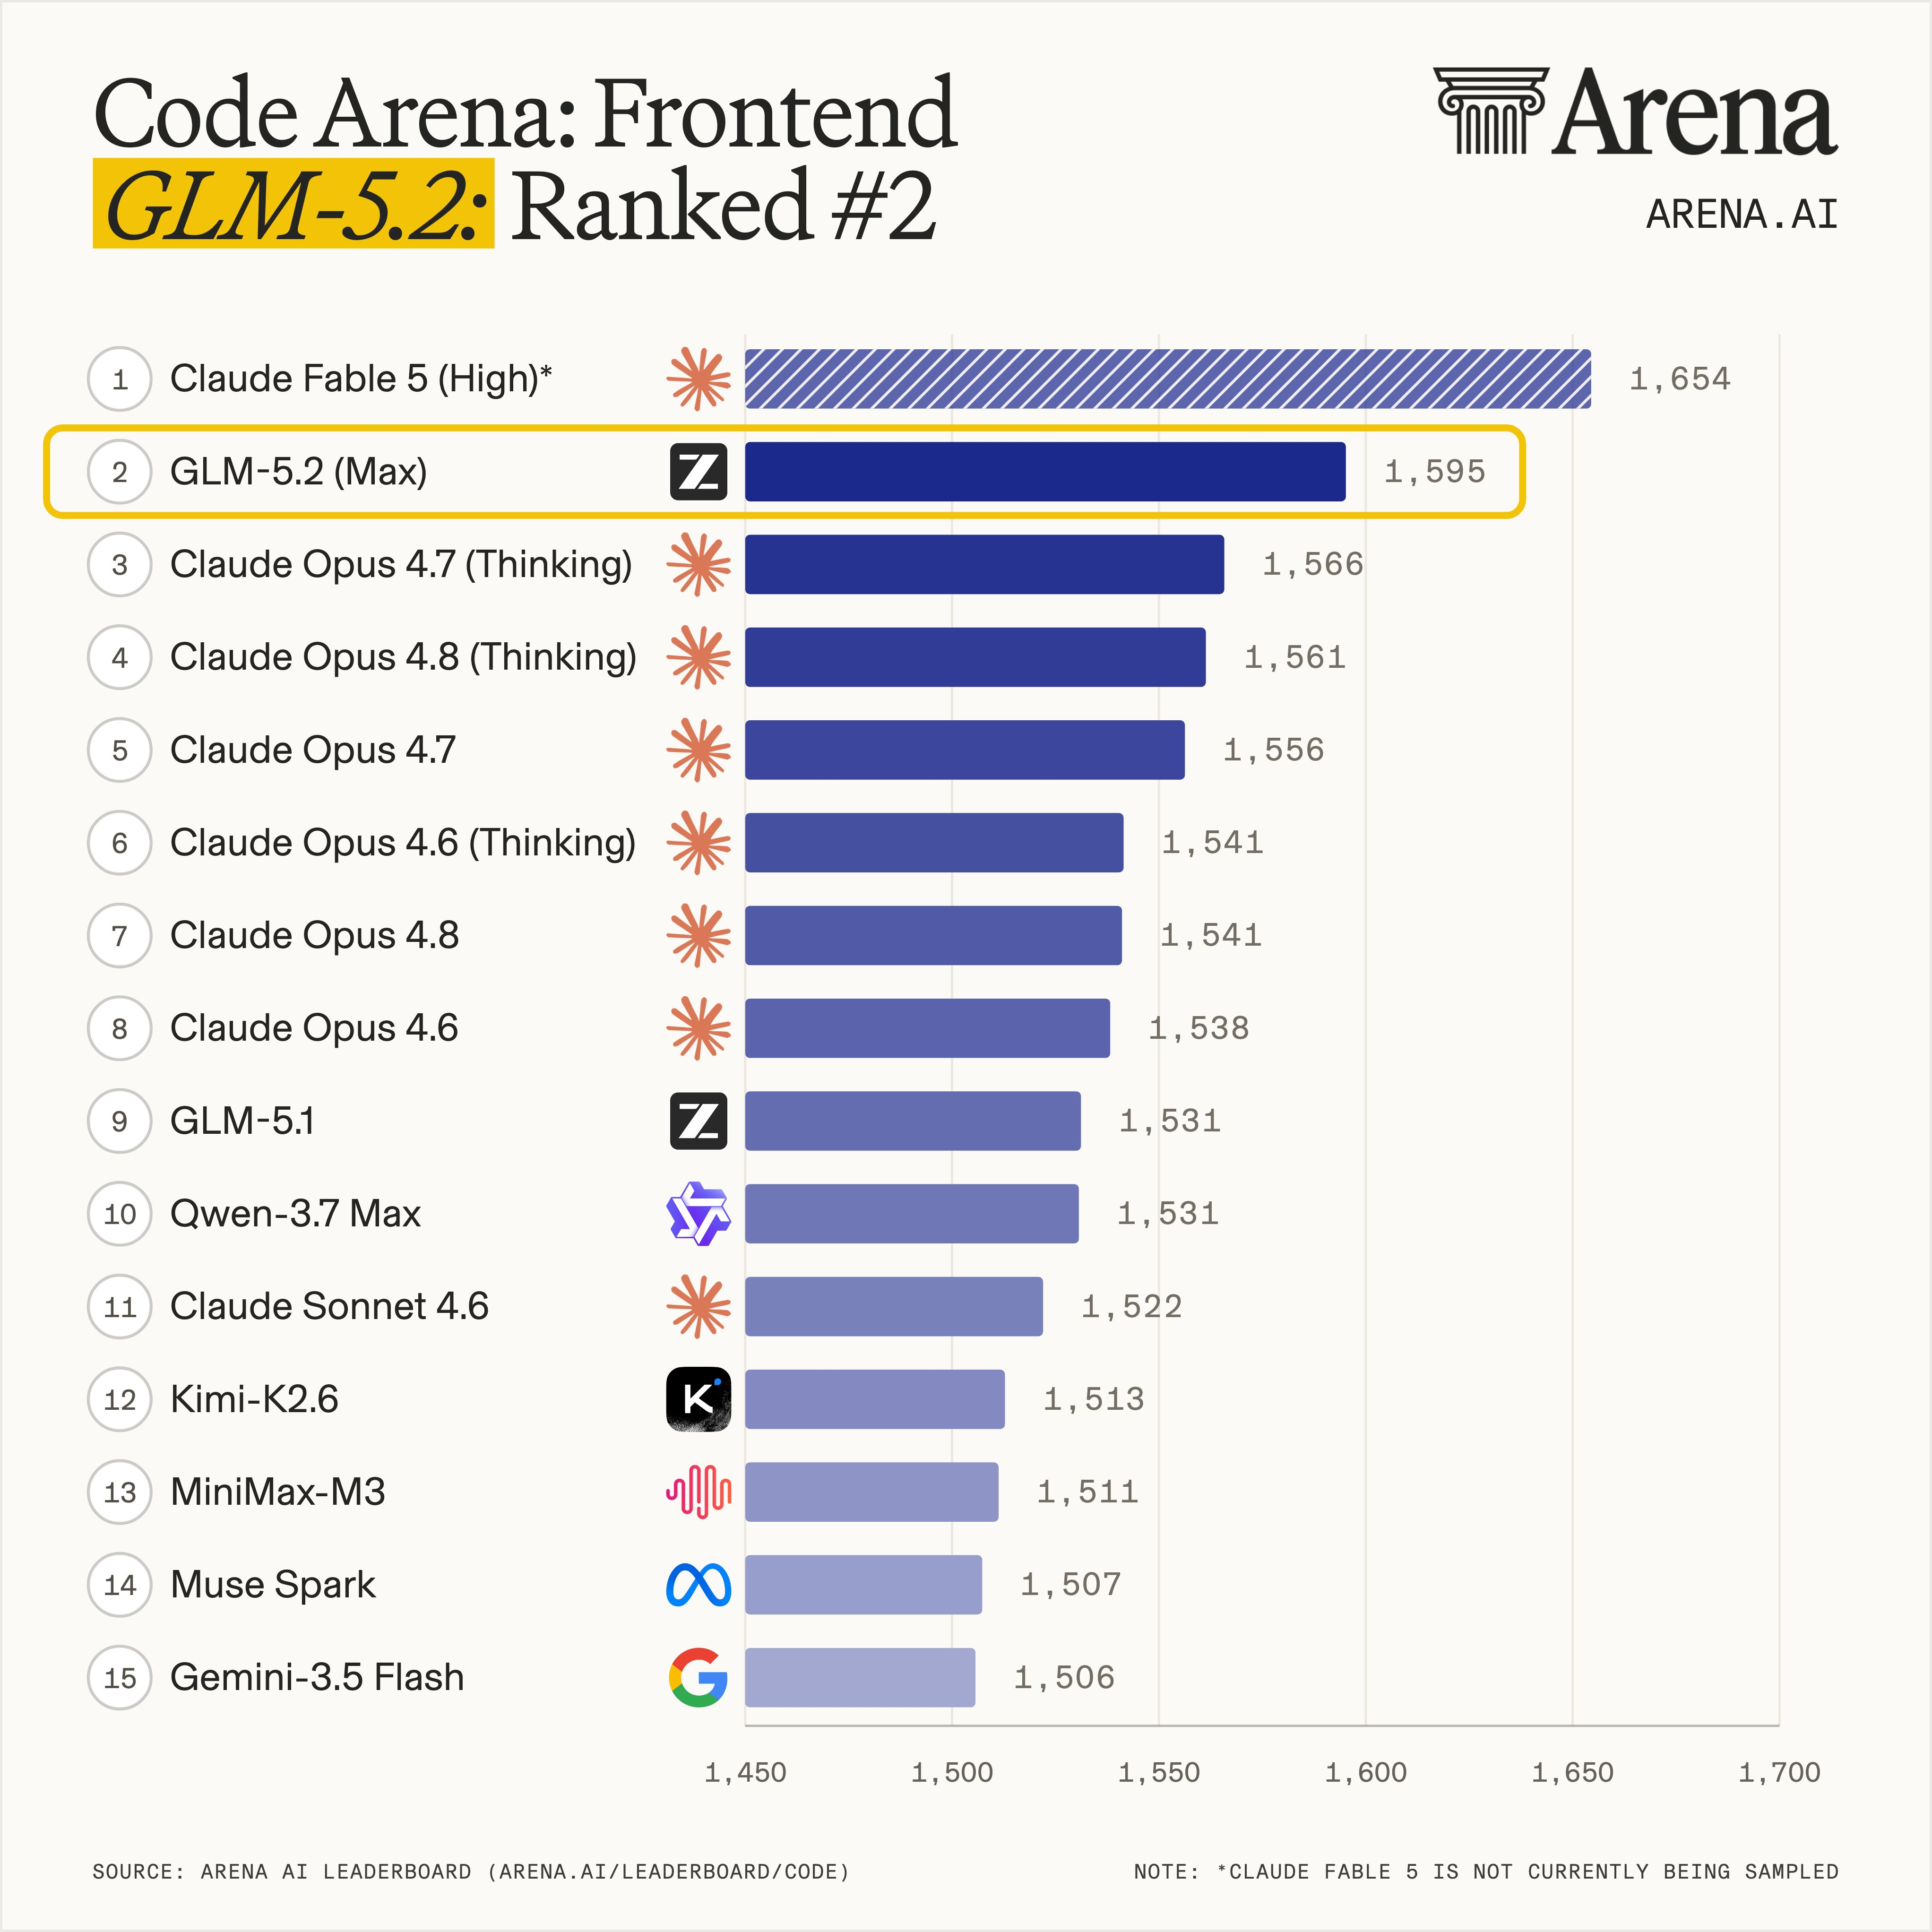
GLM-5.2 for Project-Scale Engineering
GLM-5.2 is our flagship foundation model, purpose-built for work that spans hours rather than minutes. It carries a genuine 1M-token lossless context and up to 128K output tokens, so a single chain of reasoning can hold an entire codebase. Tuned for long-range coding agents, it handles large-scale builds, automated research and performance tuning while engineering conventions stay intact across extended sessions.
- Genuine 1M ContextFeed an entire repository into GLM-5.2 — the 1M-token window stays coherent through project-level engineering and multi-hour runs.
- Top-Tier CodingIt holds open-source SOTA on leading coding benchmarks and currently sits first worldwide on Code Arena among models in circulation.
- Production DisciplineCode style, architectural boundaries and dependency rules are respected consistently, so output drops straight into real pipelines.
Start Building with GLM-5.2 in 3 Steps
Wire up the endpoint, describe what you need, and let the model return deployable output — it only takes three quick moves.
Capabilities Packed Into GLM-5.2
Multiple reasoning modes, live streaming, tool calling, context caching, structured responses and MCP connectivity all come standard with GLM-5.2.
Multiple Reasoning Modes
Switch depth on demand — it scales its thinking to match anything from a quick fix to a full architecture review.
Live Streaming Responses
Tokens arrive as they are produced, so interfaces feel instant instead of leaving users on a spinner.
Tool & Function Calling
GLM-5.2 decides which external services to invoke and formats each call, wiring your app into third-party tools.
Smart Context Caching
Repeated context is cached automatically, cutting latency and cost on the long conversations it is built for.
Structured JSON Output
Ask for JSON or another schema and it returns the shape cleanly, so downstream systems parse without repair work.
MCP Connectivity
Plug in MCP servers and the model reaches live data sources and tools, widening what a workflow can touch.
GLM-5.2: Your Questions Answered
Quick answers on context limits, coding strength and what this model can realistically build.
What exactly is GLM-5.2?
GLM-5.2 is a flagship base model built for long-horizon work. It pairs a genuinely usable 1M-token context with 128K max output tokens, which makes project-level engineering practical in a single run.
What kinds of work can it handle?
Project-scale engineering, long-range refactors, real-device mobile debugging, mini-program and mini-game builds, plus replication of research code all fall within scope.
How quickly does it respond?
Streaming output plus context caching keep responses fluid on extended sessions — long-range jobs run without the usual stall between turns.
Does GLM-5.2 write production-quality code?
On mainstream coding benchmarks GLM-5.2 holds open-source SOTA, and it currently ranks first on Code Arena among available models — on par with Claude Opus 4.8.
How much context can GLM-5.2 hold?
It offers a solid 1M-token lossless window, enough to keep a complete project context in view while accuracy stays stable.
Which project types fit it best?
Web apps, mobile apps, WeChat mini-programs, mini-games, research code replication and coding-to-video pipelines are all a strong match.
Put GLM-5.2 to Work Today
Spin up your first task with GLM-5.2 and see what a genuinely usable 1M-token context does for your next build.